Working notes, in the open.
Working notes from the studio: hypotheses, experiments and numbers from real projects. We publish them even when the result is inconvenient.
15 Sep 2026·AI and automation
AI Audits for SMEs: Choose the Workflow Before the Model
How to assess a business process before introducing AI: data, permissions, verification, cost, and practical criteria for an SME AI audit.
11 Sep 2026·AI and automation
AI Agents Need a Workspace, Not Just a Model
Why reliable AI agents need context, tools, permissions, checkpoints and verification: the operational workspace that turns autonomy into useful work.
5 Sep 2026·
GPT-6 Astra or Claude Fable 5.1? How to Choose an AI Model for Your Business
GPT-6 Astra and Claude Fable 5.1 have comparable headline API pricing. Here is how to choose an AI model for a business by looking at workflow, real cost, and reliability.
5 Sep 2026·AI and automation
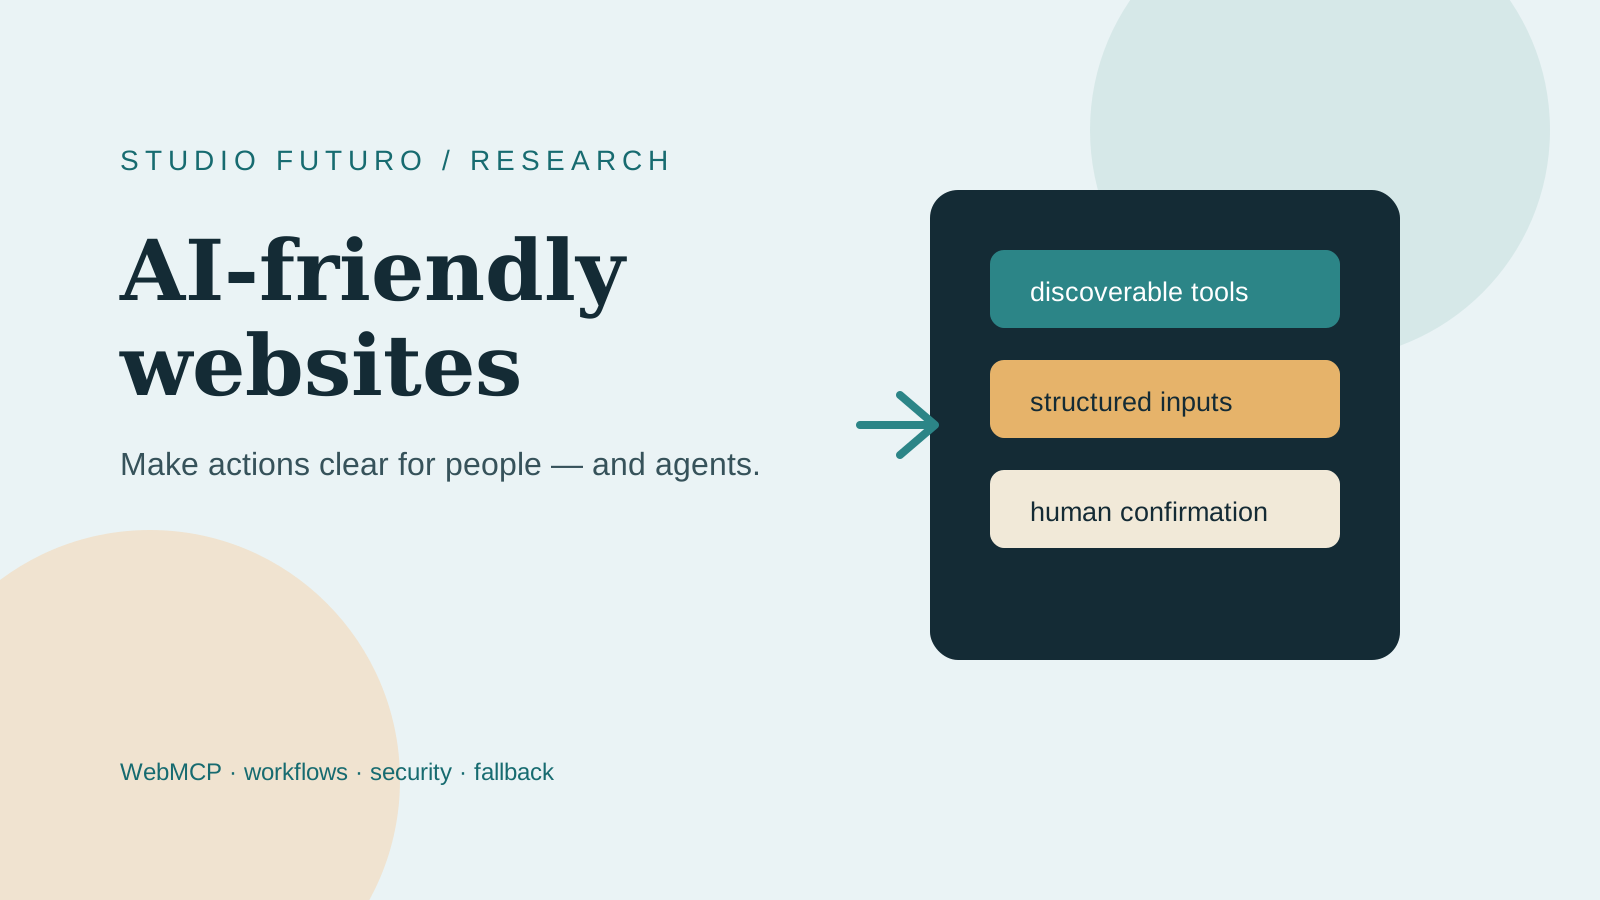
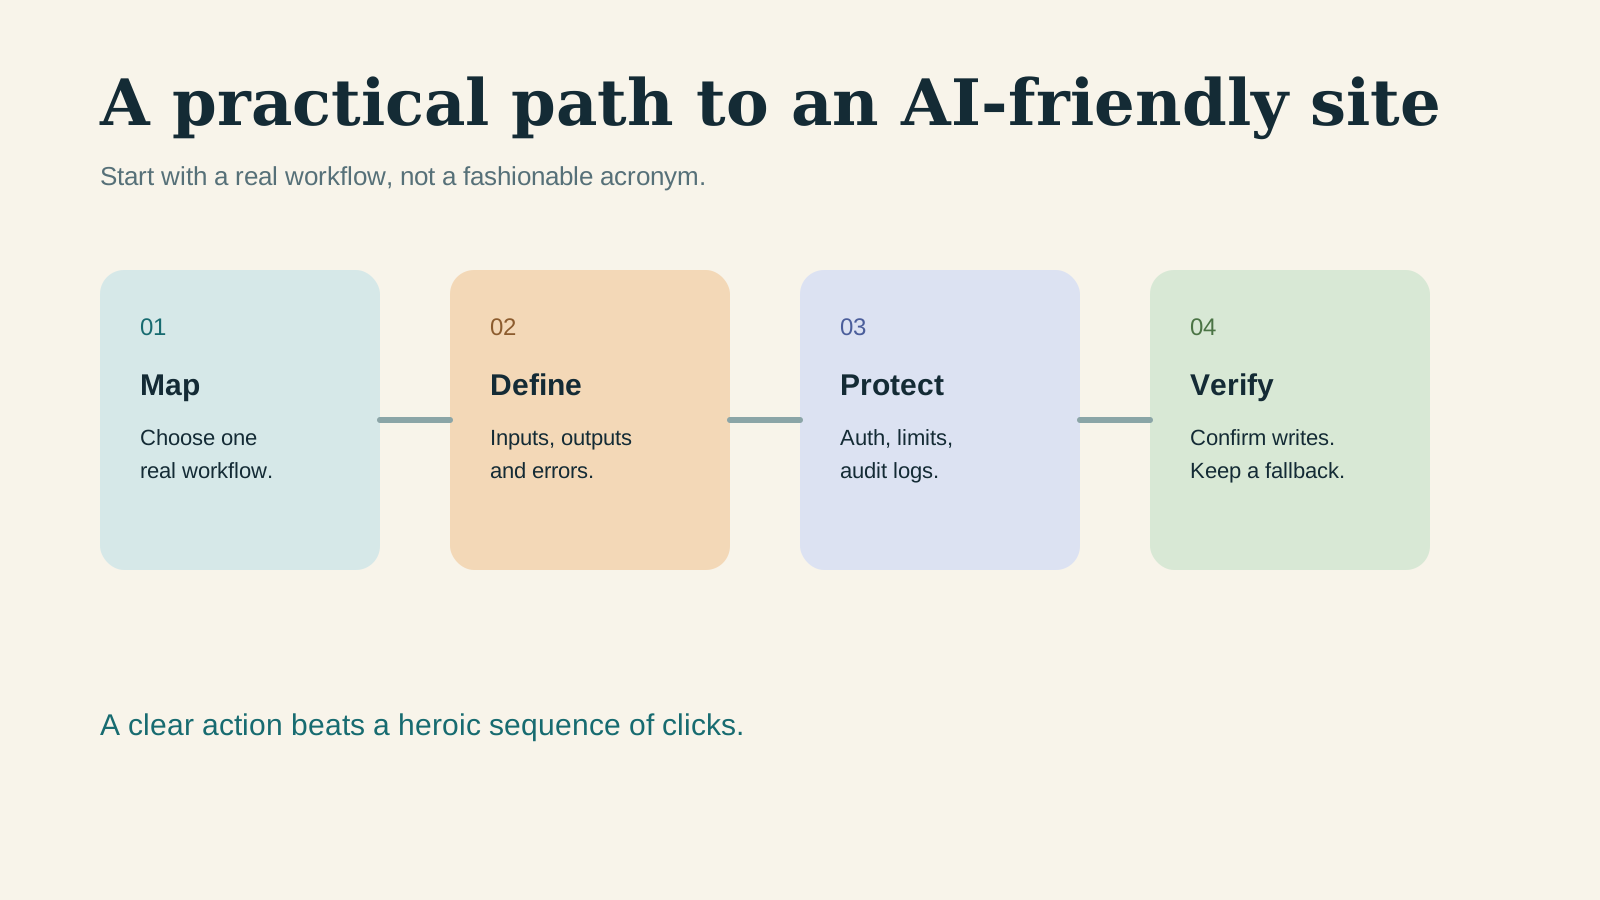
A Website Should Not Only Look Good: It Should Be Understandable to AI Agents
How Studio Futuro designs AI-friendly websites with structured actions, security, and a practical path toward WebMCP.
31 Aug 2026·AI and automation
Pi Agent and Autonomous AI Agents: How Coro Works
Learn how Pi Agent can become the runtime for a team of specialized AI agents, each with its own dedicated computer. The concrete example of Coro.
17 Aug 2026·Case study
AI-built ecommerce for schools: 40 stores live in three months | Kyron case study
Between May and August 2026 we built Kyron's brand, site, operations studio and an AI-driven ecommerce system. Today a salesperson launches a school's dedicated store alone, with no developer. Forty stores live.


20 Jun 2026·Education
AI in Italian schools: from DM 166 to the first real deployments
DM 166 and DM 219 made school principals formal deployers of AI systems, with PNRR funds up to €50,000 per school. Whoever builds for education must design governance first.
15 Jun 2026·Research
Hybrid fleets: local models and frontier APIs under one orchestrator
The studio's local pipeline was updated to the new open-weight generation — Qwen 3.5, Gemma 4, DeepSeek V3.2 — served via vLLM with speculative decoding. On repetitive workloads, local models now reach practical parity with the frontier APIs of a year ago, and speculative decoding cuts latency by a further ~40%. The studio's router treats local and cloud as a single fleet: the boundary moves per task, not on principle.
Every note has its own page. Write to us if you want a preview on a specific topic.

A meeting
Let's talk about your project
You tell us what you're building, where you're stuck, and what needs to work. If it makes sense, we define a first concrete piece.
Reply within 24 business hours